
This blog post is part 2 in a series about converting spreadsheet data into JSON and indexing it into Sitecore Search. To read the part 1, click here.
Welcome back to the final part of my two part series on turning spreadsheets into Sitecore Search indicies! In the first part, I talked about how I uploaded the spreadsheets into Sitecore via a Sitecore Powershell script and converted the data into JSON media items. In this part, we’ll talk about how I then indexed that data into Sitecore Search.
Part 2 – Ingest and Index
At this point I had gotten the JSON media items sitting in Sitecore, but Sitecore Search doesn’t know they exist. These aren’t pages, nor would I want to them to appear in my regular sitemap index. As such, I decided to create some new sources (and associated entities) in Sitecore Search for each different grouping of spreadsheets I had uploaded. For example, I had one source for contractor data, another for vendor data, and so on.
I decided on using the API Crawler source type for these.
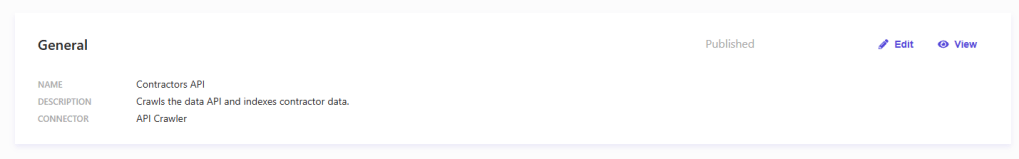
But in order for SItecore search to learn about the JSON data, I needed to give it some urls to read.
Sitecore Search’s “Request” source type is built for exactly this: you give it a URL (or, more usefully, a script that generates URLs), it fetches whatever’s there, and hands the response to a document extractor to turn into search documents.
Because a single “type” of data might be split across multiple part-files (per media item splitting from part 1), a single fixed URL isn’t enough; the crawler needs to first discover how many files exist and what’s in each, then fetch each one individually. That’s a two-endpoint dance.
Endpoint #1 – The Metadata
Given a file name (really, a data type), this endpoint queries Sitecore’s GraphQL Edge API for every media item in the JSON output folder whose name matches the main file plus any numbered parts, and reads back each one’s “Keywords” field (which lists the sheet keys that file contains). It responds with a normalized list of segments, each one carrying its part number and the sheet names it holds.
For example:
/api/path/to/endpoint/metadata?fileName=Qualified-Heat-Pumps
Might give me an output like:
{ "fileName": "Qualified Heat Pumps", "totalSegments": 3, "segments": [ { "segment": 0, "itemName": "Qualified Heat Pumps", "sheetNames": ["qualified_windows"] }, { "segment": 1, "itemName": "Qualified Heat Pumps 1", "sheetNames": ["air_source_heat_pumps"] }, { "segment": 2, "itemName": "Qualified Heat Pumps 2", "sheetNames": ["air_source_heat_pumps"] } ]}
This uses Sitecore GraphQL querying with cursor-based pagination. It verifies the API actually returned a pagination cursor when it said there were more pages, and throws an error if two segments ever resolve to the same number, rather than silently overwriting one in the response.
Endpoint #2 – The Data
Given a file name (and optionally a segment number and a specific sheet), this one fetches the actual JSON media file straight from the Sitecore Edge media delivery URL, and reshapes each row before handing it back: it stamps every object with its spreadsheet type (and sub-type, if the sheet name carries one), and can optionally can geocode address-shaped fields through a geocoding API to attach latitude/longitude.
I made that geocoding step opt-in per request rather than baked into the import script, since it’s a paid external call and I didn’t want to execute it on every data type, only for the ones whose associated search component extractor actually needed coordinates for a map view or distance check.
Both endpoints sit behind a shared-secret header check (x-api-key) rather than being left open, for good measure!
The Request Extractor
Next up was to start gluing everything together. Now that I had the metadata URLs to work with, I could create document extractors for Sitecore Search to accurately compile a list of all data urls to parse through. I only used request extractors for datasets that were segmented across multiple media items (or were on the verge of it). For small datasets that weren’t close to the threshold, I skipped this step and just listed the data endpoint URLs in those sources’ triggers instead.
For those large sets, I set the trigger URLs to the metadata URL for each particular set and then used the request extractor to determine the true list of data urls to parse through.
In the request extractor, I simply parsed through the response from the metadata endpoint set in the trigger and looped through the segments to compile the list:
for (var i = 0; i < metadata.segments.length; i++) { var segment = metadata.segments[i]; if (!segment || !Array.isArray(segment.sheetNames)) { continue; } for (var j = 0; j < segment.sheetNames.length; j++) { var sheetName = segment.sheetNames[j]; if (!sheetName) { continue; } var url = baseUrl + "?fileName=" + encodeURIComponent(fileName) + "&sheetName=" + encodeURIComponent(sheetName); if (Number(segment.segment) > 0) { url += "&segment=" + encodeURIComponent(String(segment.segment)); } requests.push({ url: url, method: "GET", headers: { "x-api-key": API_KEY } }); } }
Now that it had the list of URLs, it then moved on to request each one against the document extractor.
The Document Extractor
The last piece was to actually map the JSON data to Sitecore Search attributes. Each data type contractors, vendors, etc. had meaningfully different source fields (a contractor row and a vendor row share almost nothing), but the search index wants a consistent document shape to filter and facet against. So each source gets its own small extractor script that reads the crawled JSON, branches on the row’s spreadsheet_type, and maps whatever fields that type actually has into a common output shape: an id, a name, a type, normalized contact fields, array fields for anything facetable, and a location: { lat, lon } block when coordinates are available.
Within these extractors, I created a few small normalization helpers such as normalizeWebsite() that adds a scheme if it’s missing and filters out placeholder “N/A” values, a createId() that slugifies whatever fields uniquely identify a row, and light zip-code padding (a spreadsheet value that lost its leading zero when it got read as a number comes back as 1234 instead of 01234 — a one-line fix, but one you’ll hit constantly if your source data has any Northeast US zip codes flowing through a numeric-typed spreadsheet cell).
I considered doing these at the JSON conversion level or the endpoint level, but I found it easier to differentiate specific type cases in the individual document extractors as opposed to adding exceptions in more generic places.
Once those extractors were in place all that was left was to index the content which worked beautifully! I was then free to query the data as needed through my various search components.
The Takeaway
While I did run into some challenges along the way, I was happy that my initial plan stayed true to course and worked out pretty close to how I expected it to. While I had more issues when it came to importing the data, the Sitecore Search side of things was pretty easy to get working correctly. I’m glad to have had the experience to build this tool, and it’s definitely helped to sharpen my skills on both ends!
Thanks for joining me for this two part series! If you have any questions regarding the topics in either part, feel free to leave me a comment and I’ll get back to you as soon as I can!
Until next time,
Happy Sitecoring!

 Patt's Sitecore Blog

Leave a comment